Huawei Targets 15,488 Chips in New AI Cluster
Huawei plans a massive AI system with 15,488 chips to rival Nvidia, targeting 2027 release for training and inference variants.
Key points
- Huawei's Atlas 960 SuperPoD targets 15,488 chips and 30 EFLOPS FP8 performance for large-scale AI training.
- The Ascend 960DT chip is scheduled for Q1 2027 for training, while the 960PR variant is set for Q3 2027 for inference.
- The system uses near-packaged optics to improve data transfer efficiency across 220 cabinets covering 2,200 square meters.
Huawei is reportedly unveiling its Ascend 960 SuperPoD at Huawei Connect 2026 in Shanghai. The announcement shifts the company's competitive focus from individual chip speed to the performance of the entire computing system. By integrating thousands of accelerators, memory, and networking into one logical machine, Huawei aims to address the bottlenecks that limit large-scale AI model training.
According to reporting by NeoTeo, the strategy is clear: compete with Nvidia not just through a faster accelerator, but through the full infrastructure that connects them. The system is designed to handle models with up to 10 trillion parameters, a scale where the efficiency of data movement between chips often matters more than the raw power of a single processor.
System scale drives performance gains
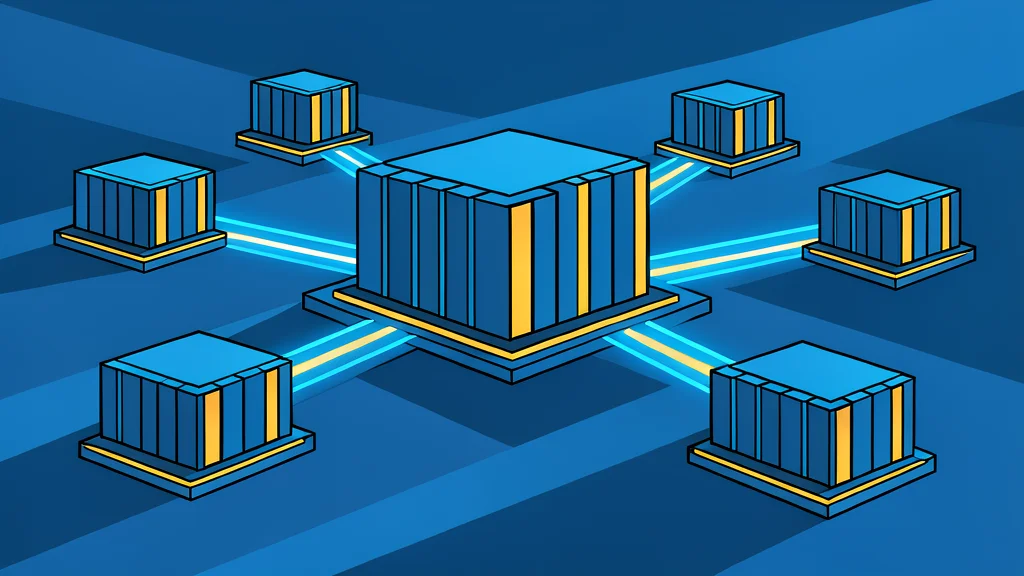
The Atlas 960 SuperPoD is a large deployment designed to combine many computing nodes. The roadmap targets up to 15,488 Ascend 960 chips distributed across 220 cabinets. This setup covers 2,200 square meters and is engineered to deliver 30 EFLOPS of performance in FP8 precision. The goal is to create a unified platform where accelerators, memory, and interconnects work seamlessly together.
This approach addresses a critical challenge in AI infrastructure: the network often becomes the bottleneck. If thousands of accelerators cannot exchange data quickly, the system slows down. Huawei's design emphasizes near-packaged optics to place optical connectivity closer to the hardware, helping move data through the large-scale system efficiently.
Two chip variants arrive in 2027
The roadmap splits the Ascend 960 family into two specific variants for different tasks. The Ascend 960DT is targeted for the first quarter of 2027 and is optimized for training models. The Ascend 960PR is scheduled for the third quarter of 2027 and focuses on inference, which is the process of using a trained model to generate answers.
At the chip level, the Ascend 960 is stated to double the computing power and memory capacity of the previous Ascend 950 series. It targets 2 PFLOPS in FP8 precision. While these are planned milestones rather than completed rollouts, they indicate Huawei's intent to maintain an annual generation cycle, with the Ascend 970 planned for 2028.
Trade-offs in precision formats
The system targets 60 EFLOPS in FP4 precision, a lower-bit numerical format. Using lower-bit formats can help process certain workloads more efficiently, but it requires that the software and models support these specific data types. This is a trade-off: higher speed in compatible scenarios, but potential limitations if the application requires higher precision.
The reported unveiling highlights Huawei's commitment to system-level scaling. The usefulness of the infrastructure depends on how efficiently chips share data and how much memory the system can address as a whole. This architecture-first approach is Huawei's answer to the reality that peak chip performance alone does not determine real-world AI utility.